Skip to content

Product Design · Human & Agent Interaction

Bryan V.B. Nee-Darko

I don’t hand over slides. I build the thing — deployed, testable.

Five projects. Each one answers the same question in a different domain: where does a person stay in the loop, and where has an agent earned the right to act alone? Three of them are running. Two are concepts, and they are labelled as concepts.

The lens

Autonomy isn't a feature. It's a design decision about authority

When I design a system that works alongside people, my first question isn't what it can do. It's what it's allowed to do. What can it observe, what can it recommend, and what can it act on by itself? What stays a human call? And is that line just suggested by the interface, or built into the system so nobody crosses it by accident?

One axis

  1. Observe

    The system watches and surfaces patterns.

  2. Recommend

    It proposes, a person decides.

  3. Act

    It executes on its own, inside limits someone set.

Selected Work

Accessibility · Agent system

Concept — no shipped prototype yet

The Accessibility Agent and the Agent Factory

Someone reads the product once, writes it up, and the write-up starts going stale the same week. That is what accessibility work usually looks like. An agent could run continuously instead — but only across the part of WCAG that is actually machine-decidable. Drawing that line is the whole design problem, so I drew it before building anything: all 55 criteria, classified by what an agent can be trusted to decide.

Context

WCAG 2.2 at levels A and AA is 55 success criteria. They are usually treated as one undifferentiated checklist, which is what makes accessibility feel like an unbounded chore.

They are not one kind of thing. Some — colour contrast, name-role-value, page language — are fully decidable by a machine. Some can be detected but not judged: a tool can find an image with no alt text, but it cannot tell you whether the alt text that is there is any good. And some are pure judgement: meaningful sequence, consistent identification, error suggestion.

An agent built without that distinction will mark a page as passing when it is not — and a false pass is worse than no audit at all, because a gap eventually gets found while a false pass just gets trusted.

My role

Sole author of the concept and of the artefact below. This is my own work, unshipped.

The coverage matrix is the deliverable I would take into a build. It defines the agent's permission boundary before a line of the agent exists.

Interaction model

Human

Owns judgement and intent.

  • Decides what the product is supposed to communicate — the input no checker has.
  • Rules on every criterion classified as manual.
  • Reviews and accepts or rejects each partial finding.
Handoff

The matrix is the contract.

  • full — the agent may detect, fix, and open a pull request with the evidence. A person merges it.
  • partial — the agent may detect and draft, but must return it flagged.
  • manual — the agent may only route it to a person, with context. It may never mark it passed.
Agent

Runs continuously, inside the boundary.

  • Checks on every commit rather than once per quarter.
  • Proposes patches as reviewable diffs, never silent edits.
  • Writes the evidence trail: what was checked, what was decided, by whom.

The artefact

WCAG 2.2, levels A and AA. Filter, search and sort it.

Those three figures are out of 56 classified paths, not 55 criteria. Where the honest answer depends on the situation, a criterion is classified once per scenario and therefore appears in more than one class.

Level
Automatability

Showing 55 of 55 criteria.

55 of 55 classifications reviewed.

WCAG 2.2 levels A and AA. All 55 success criteria, classified by how much of each one an agent can decide without a person. 56 rows in total: a criterion whose answer depends on the situation is split into scenario rows that share one criterion number.
Why
1.1.1Non-text ContentAPartialDetecting a missing alt attribute is trivial. Judging whether the alt text conveys the same purpose is not.
1.2.1Audio-only and Video-only (Prerecorded)APartialThe presence of an alternative can be checked. Its equivalence cannot.
1.2.2Captions (Prerecorded)APartialA caption track's presence and timing are checkable. Accuracy needs a person.
1.2.3Audio Description or Media Alternative (Prerecorded)AManualRequires watching the content and deciding what visual information a listener loses.
1.2.4Captions (Live)AAManualLive output cannot be evaluated before it exists.
1.2.5Audio Description (Prerecorded)AAManualRequires judging what a sighted viewer receives that a listener does not.

Agent Factory

How the classification becomes a permission boundary.

  1. Step 01

    Specification

    The coverage matrix is the input, not documentation about the input. Each of the 55 criteria carries its permission class, and that class is what the factory reads.

  2. Step 02

    Factory

    One narrow agent is generated per criterion from a shared template: a detector, a patcher, and an evidence writer. A criterion classified manual gets a detector and a router — no patcher is generated at all.

  3. Step 03

    Fleet

    The agents run per commit rather than per quarter. Each one has a single testable definition of correct, so a regression points at one agent instead of at accessibility in general.

What each class is allowed to do

Not every accessibility issue should be fixed by an agent. Some fixes are mechanical. Others need someone who understands what the page is for. So the agent’s permissions depend on the kind of issue, not on how confident it feels about one.

Full
detect → fix → open a pull request with the evidence.
Partial
detect → draft → return it flagged, a person accepts or rejects.
Manual
detect → explain → route to a named person, never record a pass.

The highest authority this agent has stops before the merge. There is no class that lets it change the product on its own.

And this isn’t an instruction the agent is asked to follow. The class decides what gets built: an agent for a manual criterion is generated with a detector and a router and no patcher at all, so there is no code path that could mark it passed. A capability that needs judgement is never handed over in the first place.

Decisions

Classify conservatively. When a criterion is arguable, it drops to manual.

Because
A false pass on accessibility is more damaging than a gap, because the gap gets fixed and the false pass gets trusted.
What it costs
Lower automation coverage and more human hours than an optimistic classification would claim.

An Agent Factory of narrow, single-criterion agents rather than one general accessibility agent.

Because
A narrow agent has a testable definition of correct. A general one only has an opinion.
What it costs
More surface to build and maintain, and an orchestration layer that a single agent would not need.

What could go wrong

The agent confidently changes something that needed context, and the page ends up less accessible than it was.

Authority
Whether a fix needs context is settled by the criterion's class, before the agent exists. The agent never makes that call at run time.
Guardrail
An agent for a manual criterion is generated without a patcher, so there's no code path that could make the change. And even at its widest class, the agent stops at a pull request.
Recovery
One agent covers one criterion, so a regression points at a single agent instead of at accessibility in general. The evidence trail records what was checked, what was decided, and by whom.

Result

Artefact
All 55 criteria classifiedFilterable, sortable, and on this page — not in a PDF.
Status
ConceptNo prototype has been built. Said here rather than implied.

Complex desktop product · Live

Live — running, in use, embedded below

ICS Playlist Studio, and the discipline of a read-only mode

Ten minutes before a class, an instructor is still assembling the set. Ninety seconds into it, they are riding it live, with a room watching. Generating a good playlist for indoor cycling turned out to be straightforward. Serving the same person in both of those states — authoring and operating — did not.

Context

Indoor Cycling Stuttgart runs strength rides: music mapped to a ride structure, with cadence, intensity blocks and leadership cues. Building one by hand is an hour of work.

The operating conditions are the real constraint. Instructors finish a set minutes before a class, in a studio, on a phone, with a room filling up. Then the class starts and the context inverts: they are no longer editing, they are executing, in front of twenty people, with no attention to spare.

A single interface that serves both states serves neither.

My role

Product design and build. Sole designer and engineer.

Responsible for the generation model, the studio interface, the Ride Mode split, and the deployment you can open below.

Interaction model

Human

Stays the author.

  • Sets the ride intent: type, structure, duration, the cues that make it theirs.
  • Edits every generated block. The draft is a starting point, not a verdict.
  • Decides when the set is finished and the ride begins.
Handoff

Two seams, not one.

  • Generation → authoring: the system returns a complete but fully editable draft. It never publishes on its own.
  • Authoring → Ride Mode: crossing this seam is a deliberate act, and it removes every editing capability.
  • Ride Mode offers no way to modify or delete.
Agent

Proposes structure, keeps time, commits nothing.

  • Maps ride structure to track selection and block timing.
  • Produces a coherent whole rather than a list of suggestions.
  • Holds the beat for the whole ride, so the room stays in time and the instructor calls it instead of counting it.
  • Can change nothing during a ride. Keeping time is the only authority it has there.

Authority model

Two modes, and what each one puts within reach.

An instructor has two jobs that never happen at the same time: building a session, and running it in front of a room. So the app has two modes, and they don’t have the same powers.

What the authoring mode and Ride Mode each put within reach
CapabilityAuthoringRide
ViewAvailableAvailable
NavigateAvailableAvailable
ModifyAvailablenot offered
DeleteAvailablenot offered

A confirmation dialog still allows an unsafe action. It just adds a step in front of it. In Ride Mode, editing isn’t hidden behind a warning — the mode doesn’t put it in reach at all.

The system can suggest changes to a session. Nothing goes in until the instructor accepts it.

Live demo

The read-only Ride Mode deployment, embedded.

The demo is a full application. It is loaded on request rather than on page load, so embedding it does not cost this page the performance it claims. It opens in read-only Ride Mode.

This is the real deployment, not a recording. Ride Mode has no write capability, which is what makes it safe to hand to a stranger. The accessibility of the embedded application is outside this page’s control — if the frame does not load, use the direct link.

Decisions

Ride Mode is strictly read-only. No edit, no save, no delete — the mode doesn't put them in reach.

Because
During a class, an accidental touch isn't a minor annoyance — it's a visible failure in front of a room of people who paid to be there, at the one moment the instructor can't look down and recover.
What it costs
An instructor who notices a mistake mid-ride genuinely cannot fix it in place. They have to leave Ride Mode to do it.

Accept that cost rather than softening the boundary.

Because
Leaving a mode is a conscious act; a mis-swipe is not.
What it costs
The recovery path is slower than it could be, and that is the point.

What could go wrong

Mid-ride, under load, the instructor taps the wrong thing and changes the session.

Authority
Changing a session is an authoring decision, never a ride decision.
Guardrail
Ride Mode doesn't put modify or delete in reach.

Result

In use
Prep collapsed to secondsPlaylist, movements and live delivery in one — each track cued about five seconds before it plays, at the same quality every ride.
Status
LiveThe embed above is the real deployment, in read-only Ride Mode.

Governance pattern · Luxury hospitality

Concept — governance model, unbuilt

Concierge OS and the CodeKeeper

A system that serves people should get better the longer it runs. This one isn't allowed to know who anyone is — no profiles, no identifiable personal data. That leaves two questions open, and they are the whole design: how does it learn anything at all, and who decides what it learns?

Context

What a place like this sells is specificity — a particular register, a particular set of things it would and would not say. That register is the asset, and it is the first thing a language model erodes. An assistant trained toward helpfulness drifts toward the mean of everything ever written in the field. The drift is slow, individually invisible, and nobody notices until the place no longer sounds like itself.

Reviewing every response would catch it, and would also destroy the speed that makes the assistant worth having. Reviewing nothing lets it compound.

So it never asks the team to write anything down while they are working. It learns from four quiet signals: what people ask for, which anticipations get accepted, which get declined, and how the rhythm shifts by suite and by time of day. The one active input window is the briefing before the shift, when nobody is with anyone yet.

Two loops carry that. In the request loop, something is asked, the system prepares, the team acts — fast, and in the moment. In the calibration loop, the CodeKeeper looks at patterns and drift over a longer stretch and decides what the system should do differently. It is slow, and it sits outside the request path.

My role

Sole author. This is a governance model, not a shipped product.

The contribution is the third option between per-request review and no review at all.

Interaction model

Human · staff

Keeps the moments that carry the reputation.

  • Handles arrival, recovery, and anything with emotional weight.
  • Is never the bottleneck for a question about timing.
CodeKeeper

Outside the request path, inside the calibration path.

  • Holds the house DNA: the written definition of how this place speaks, kept as a document a person maintains rather than as a setting inside the model.
  • Samples what actually went out and compares it against that definition.
  • Adjusts prompts, examples and boundaries. Never answers on behalf of the system.
Agent

Absorbs volume.

  • Logistics, timing, coordination, recall of a stated preference.
  • Operates within the register the CodeKeeper maintains.
  • Escalates on emotional weight rather than on confidence score.

Governance

Where the CodeKeeper sits, and where it deliberately does not.

Request loop

every request · milliseconds

  1. Ask

    Someone asks for something. Thousands of times a day.

  2. Answer· shared node

    The system responds inside the register it currently holds.

  3. Done

    The person being served has it before they notice waiting.

Closes on the person being served, with no human anywhere in it.

A sample of what went out ↓

Calibration loop

on a cadence · weeks

  1. Sample

    A slice of what actually went out — never a single response. At that resolution every answer looks fine.

  2. Aggregate

    Drift only has a shape at volume. One reply is never wrong enough to notice; two hundred are.

  3. Correct

    The register moves back before the gap compounds. Nobody waited for this.

The correction lands in the system above, then the loop samples again. It never touches a live request.

One loop runs thousands of times a day, the other a handful of times a month. That gap is the design: a single response is never wrong enough to act on, and a thousand of them are. Putting a person inside the fast loop would catch nothing and cost everything.

Judgement view

The one gate between what the system observed and what it does next.

Nothing moves from data into behaviour on its own. Every proposed change reaches the CodeKeeper as three things, and the answer is explicit — there is no default.

Observation
What the system saw in the signals.
Reading
How it interpreted what it saw.
Consequence
What follows from a yes, and from a no.

The calibration log keeps every one of those answers, so any change in the system’s behaviour can be traced back to the observation behind it and the person who accepted it.

System and CodeKeeper calibrate each other. The decisions stay with the person.

When several sites run the same system, they share patterns and never personal data.

Where the pattern applies: anywhere people can’t document while they work, and a learning system still has to hold a standard.
Decisions

The CodeKeeper sits outside the request loop and calibrates in batch, not per response.

Because
Per-request human review does not scale and removes the speed that justifies the system. No review at all lets drift accumulate silently. Calibration is the only version that survives contact with volume.
What it costs
Drift is caught late — a batch of responses can go out slightly off-register before the next calibration pass catches it.

Name it as a role a person holds, not as an automated eval.

Because
The thing being protected is taste. An automated check can only measure consistency with yesterday, which is exactly how a system drifts steadily in one direction.
What it costs
It is a standing headcount commitment, and the model depends on that person's judgement.

What could go wrong

The system learns something that fits the data and is wrong for the place.

Authority
What the system should learn is a human call.
Guardrail
A behaviour change reaches the CodeKeeper as three things: an observation, how the system read it, and what follows from a yes or a no. Nothing moves from data into behaviour without that answer.
Recovery
The calibration log holds every one of those answers, so a change in behaviour can be traced back to the observation behind it and the person who accepted it.

Result

Artefact
Governance model and role definitionThe feedback loop is diagrammed above.
Status
ConceptMine alone. Nothing has been built.

Generative image production · Working

Working system — pipeline in use

Northlight, or why the shoot became optional

Every variant of a product image used to cost another location, another crew and another day. Northlight replaces that with a Node.js pipeline on fal.ai, Blender scenes as geometric reference, and a structured split between cheap probing and expensive production. For a large class of product imagery, the shoot stops being necessary.

Context

Brand and product imagery is produced through shoots: location, crew, set, schedule. Every variant — another angle, another colourway, another season — costs another setup.

Generative models can produce the image. What they cannot do unsupervised is produce the same product, at the same angle, under the same light, two hundred times. Consistency is the entire job, and it is the thing prompting is worst at.

The design work, then, is subtractive: deciding how much of the model's freedom to remove.

My role

Built the system. Pipeline architecture, the Blender reference method, and the probe/production structure.

Working and in use — the twelve frames below are real output from it, not mock-ups.

Interaction model

Human

Art direction, upstream.

  • Decides the frame, the light and what correct looks like.
  • Builds or selects the Blender reference that fixes camera and geometry.
  • Judges the probe pass and chooses what earns a production render.
Handoff

The Blender scene is the contract.

  • Fixed by the reference: camera, framing, proportion, light direction.
  • Free for the model: surface, material response, atmosphere, grain.
  • The boundary is geometric, so it can be checked rather than argued about.
Agent

Generates at two tiers.

  • Probe: cheap, wide, many variants — used to find the direction.
  • Production: narrow, expensive, final — run only on approved probes.
  • Both are reproducible from the scene file, not from a remembered prompt.

Constraint envelope

What the reference fixes, and what the model is left free to vary.

Generative models are good at variation and bad at holding still. So everything that makes the product recognisable is fixed by a 3D reference before the model is asked for anything. Autonomy is only useful inside a space someone deliberately limited.

Which parameters the reference fixes and which the model is free to vary
Human lockedAI exploration
CameraSurface
FramingMaterial response
ProportionAtmosphere
Light directionGrain

The boundary is geometric, so it can be checked rather than argued about: the geometry either matches the reference or it doesn’t.

Checked is not the same as enforced. Nothing in the pipeline refuses a render that skipped the probe pass, and under time pressure that is exactly where it gives.

The series

Twelve production frames. Pick one to see it large.

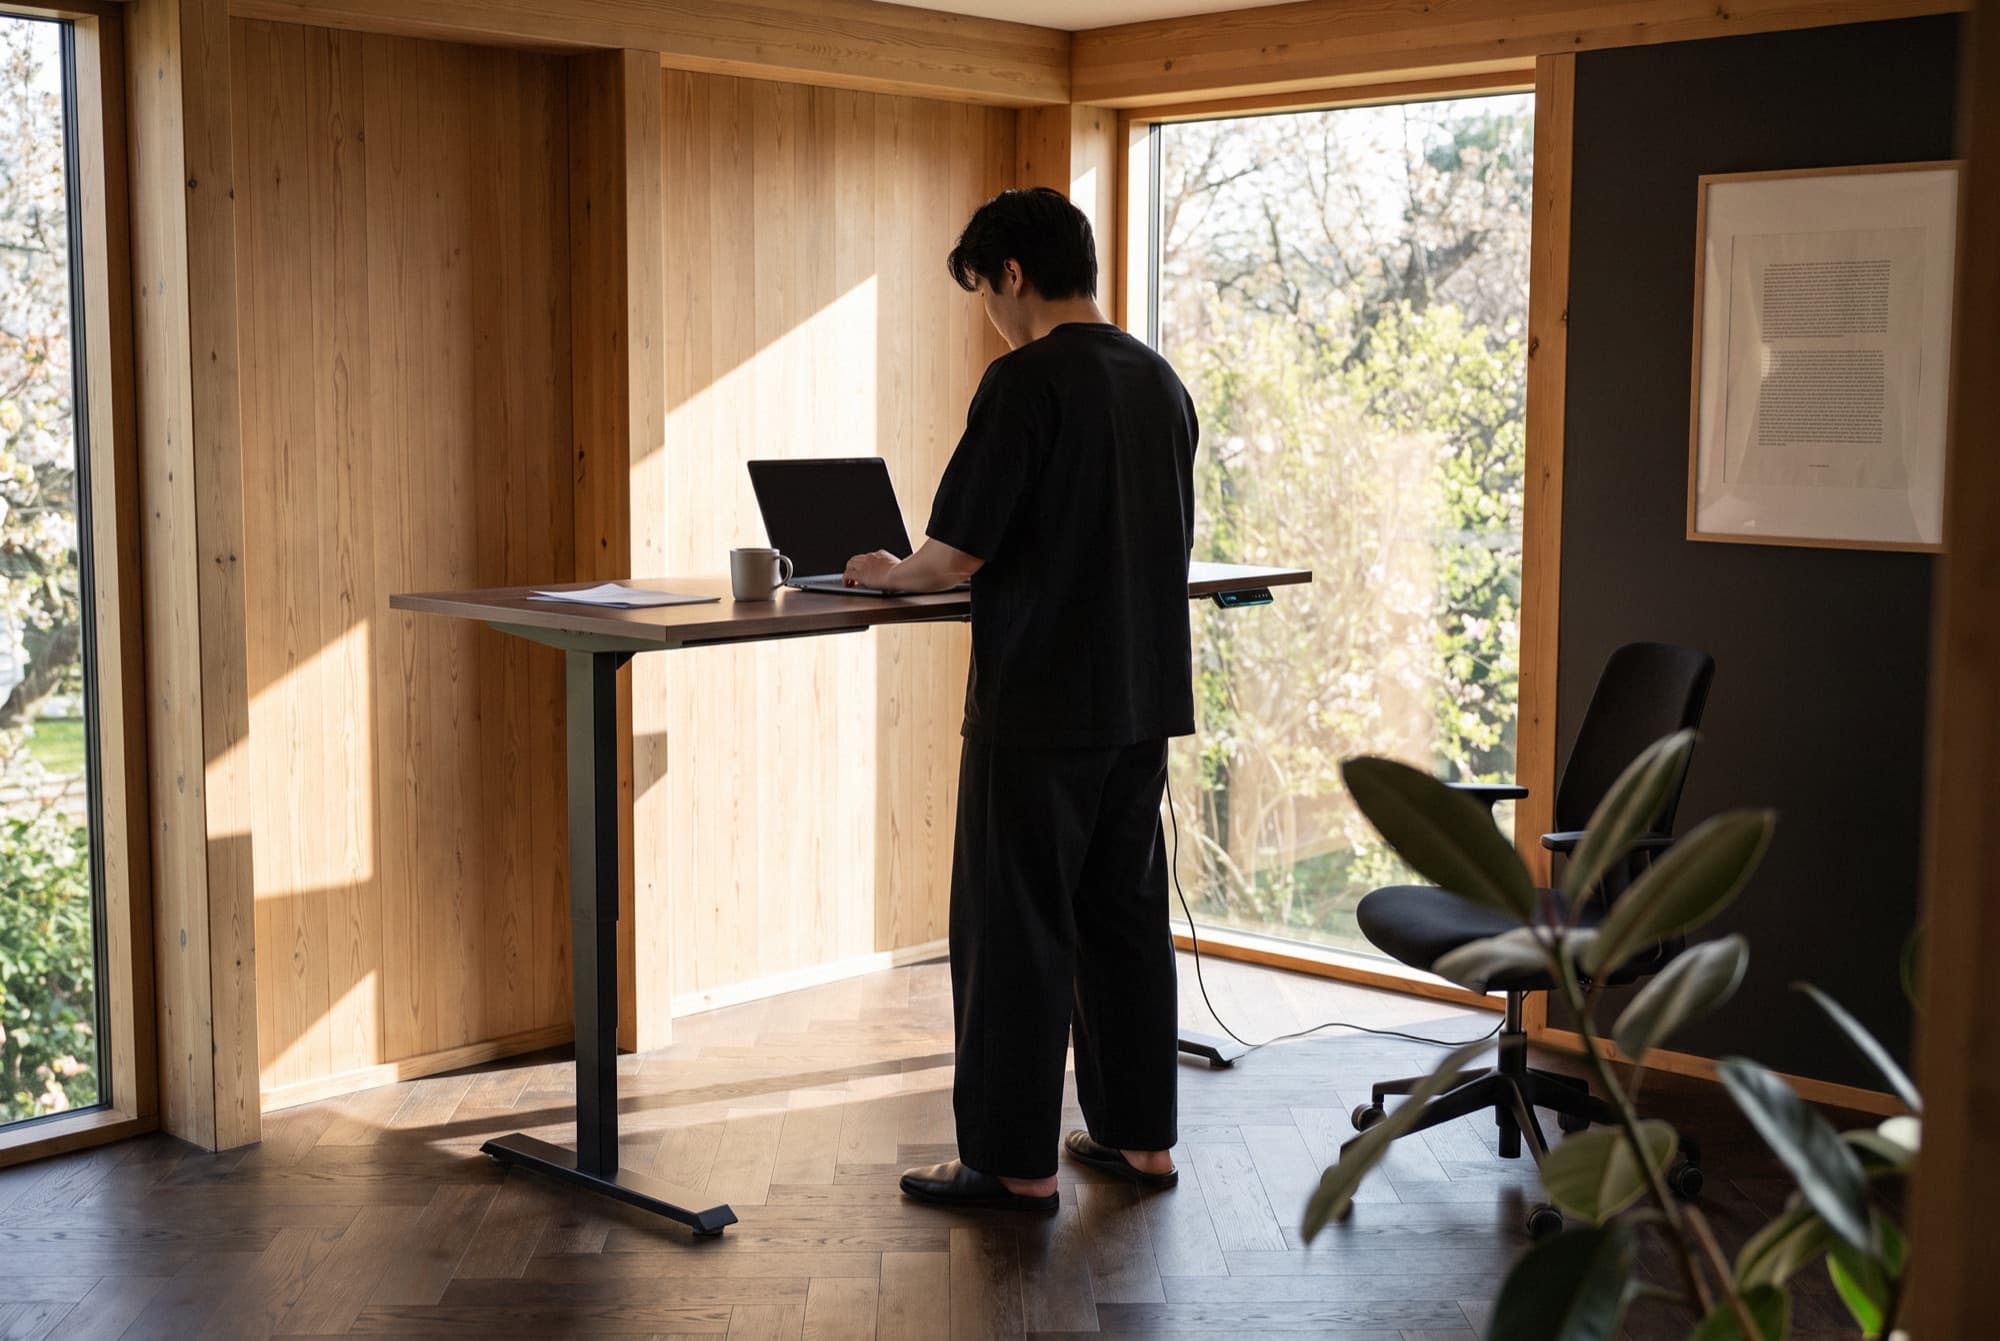
A man works standing at the desk in a timber-clad study, laptop open, tall windows onto a garden casting hard afternoon light across the floor.
Timber studyEditorial, single occupant

One product, one geometry, twelve rooms. Every frame here would have been a separate shoot — a separate location, set, crew and day. None of them was photographed.

Decisions

Constrain every generation with an explicit 3D reference instead of prompting for composition.

Because
A brand needs the same product to look like the same product across the whole set. Reproducibility is worth more than a good accident.
What it costs
Setup time per scene, and the genuinely surprising results that unconstrained prompting sometimes produces are ruled out.

Split every job into a probe pass and a production pass.

Because
Judgement should be spent on cheap output. Money should be spent only on output that has already been judged.
What it costs
An extra step in every job, and a discipline that holds only as long as the person running it holds it — which is least likely when they are in a hurry.

Result

Turnaround
Seconds per shot, not a shootOnce a scene is set, a new situation renders in seconds — no location, crew or reshoot.
Status
WorkingPipeline runs. Twelve production frames above.

Brand system · Slide compiler

Shipped — master in use

Deckforge

Designing a slide master that carries a brand is straightforward. The one I built shipped clean, looked correct, and was wrong in 48 of its 115 text roles — every box measured against a line height that no real font produces. Nothing appeared broken, which is exactly why it would have survived. What the system is built around now is the measurement that catches that.

Context

A template does not hold a brand. PowerPoint hands every user a surface and a set of handles, and the drift starts on the second deck: a headline nudged down two points so a sentence fits, a colour picked out of an older file, a margin set by eye. Nobody breaks the system deliberately. It erodes.

So the slide stops being a surface someone arranges and becomes an artefact the brand definition compiles. One definition holds colour, type scale, grid and lockups. Twenty-nine layouts read from it. No layout carries a value of its own, and type sizes are fixed — nothing scales to fit, because auto-fitting text is the reason deck families come apart. Each slide finds its own size, and after three editors the series is gone.

That decision is the whole system, and it is the one that failed quietly. Line spacing was expressed as a percentage — of the font's line height, not of the type size, which is what the layouts had assumed. Inter Tight carries 1.21 em, a serif more like 1.30. Every box in the set was therefore around twelve percent too tight for what it was meant to hold, and six roles could not fit a single line of their own style. The text did not clip. It grew into its neighbour.

Fixing the six visible cases would have been the wrong repair. Line spacing is now absolute: type size times factor, resolved before the file exists and independent of which font the recipient has installed. Every box holds its designed line count again, and not one box was enlarged. The price is real and worth stating — absolute spacing ignores font metrics, so a face with unusually tall ascenders will set tight. That is a visible error rather than a counted one, which makes it the better of the two.

My role

Sole author. The brand definition, both stages of the pipeline, and the measurement underneath them.

Delivered and in use. The artefacts below are rendered from that build with an invented brand substituted for the client's — the geometry is untouched, only colour and typeface change.

Interaction model

Author

Owns the definition and the words.

  • Sets colour, type scale, grid and lockups once, in one file.
  • Chooses the layout whose shape fits the point being made.
  • Writes to the budget of the role, rather than resizing the role.
The definition

One file is the contract.

  • Every layout reads its values from it; none carries its own.
  • Each text role carries a measured character budget, not an estimate.
  • When input doesn't fit the master, the build stops and says why. It never quietly approximates.
Compiler

Builds the master, then sets content against it.

  • Stage one generates 29 layouts from the definition.
  • Stage two places content without touching a single layout.
  • Refuses the run when content exceeds what a role was measured to hold.

The specimen

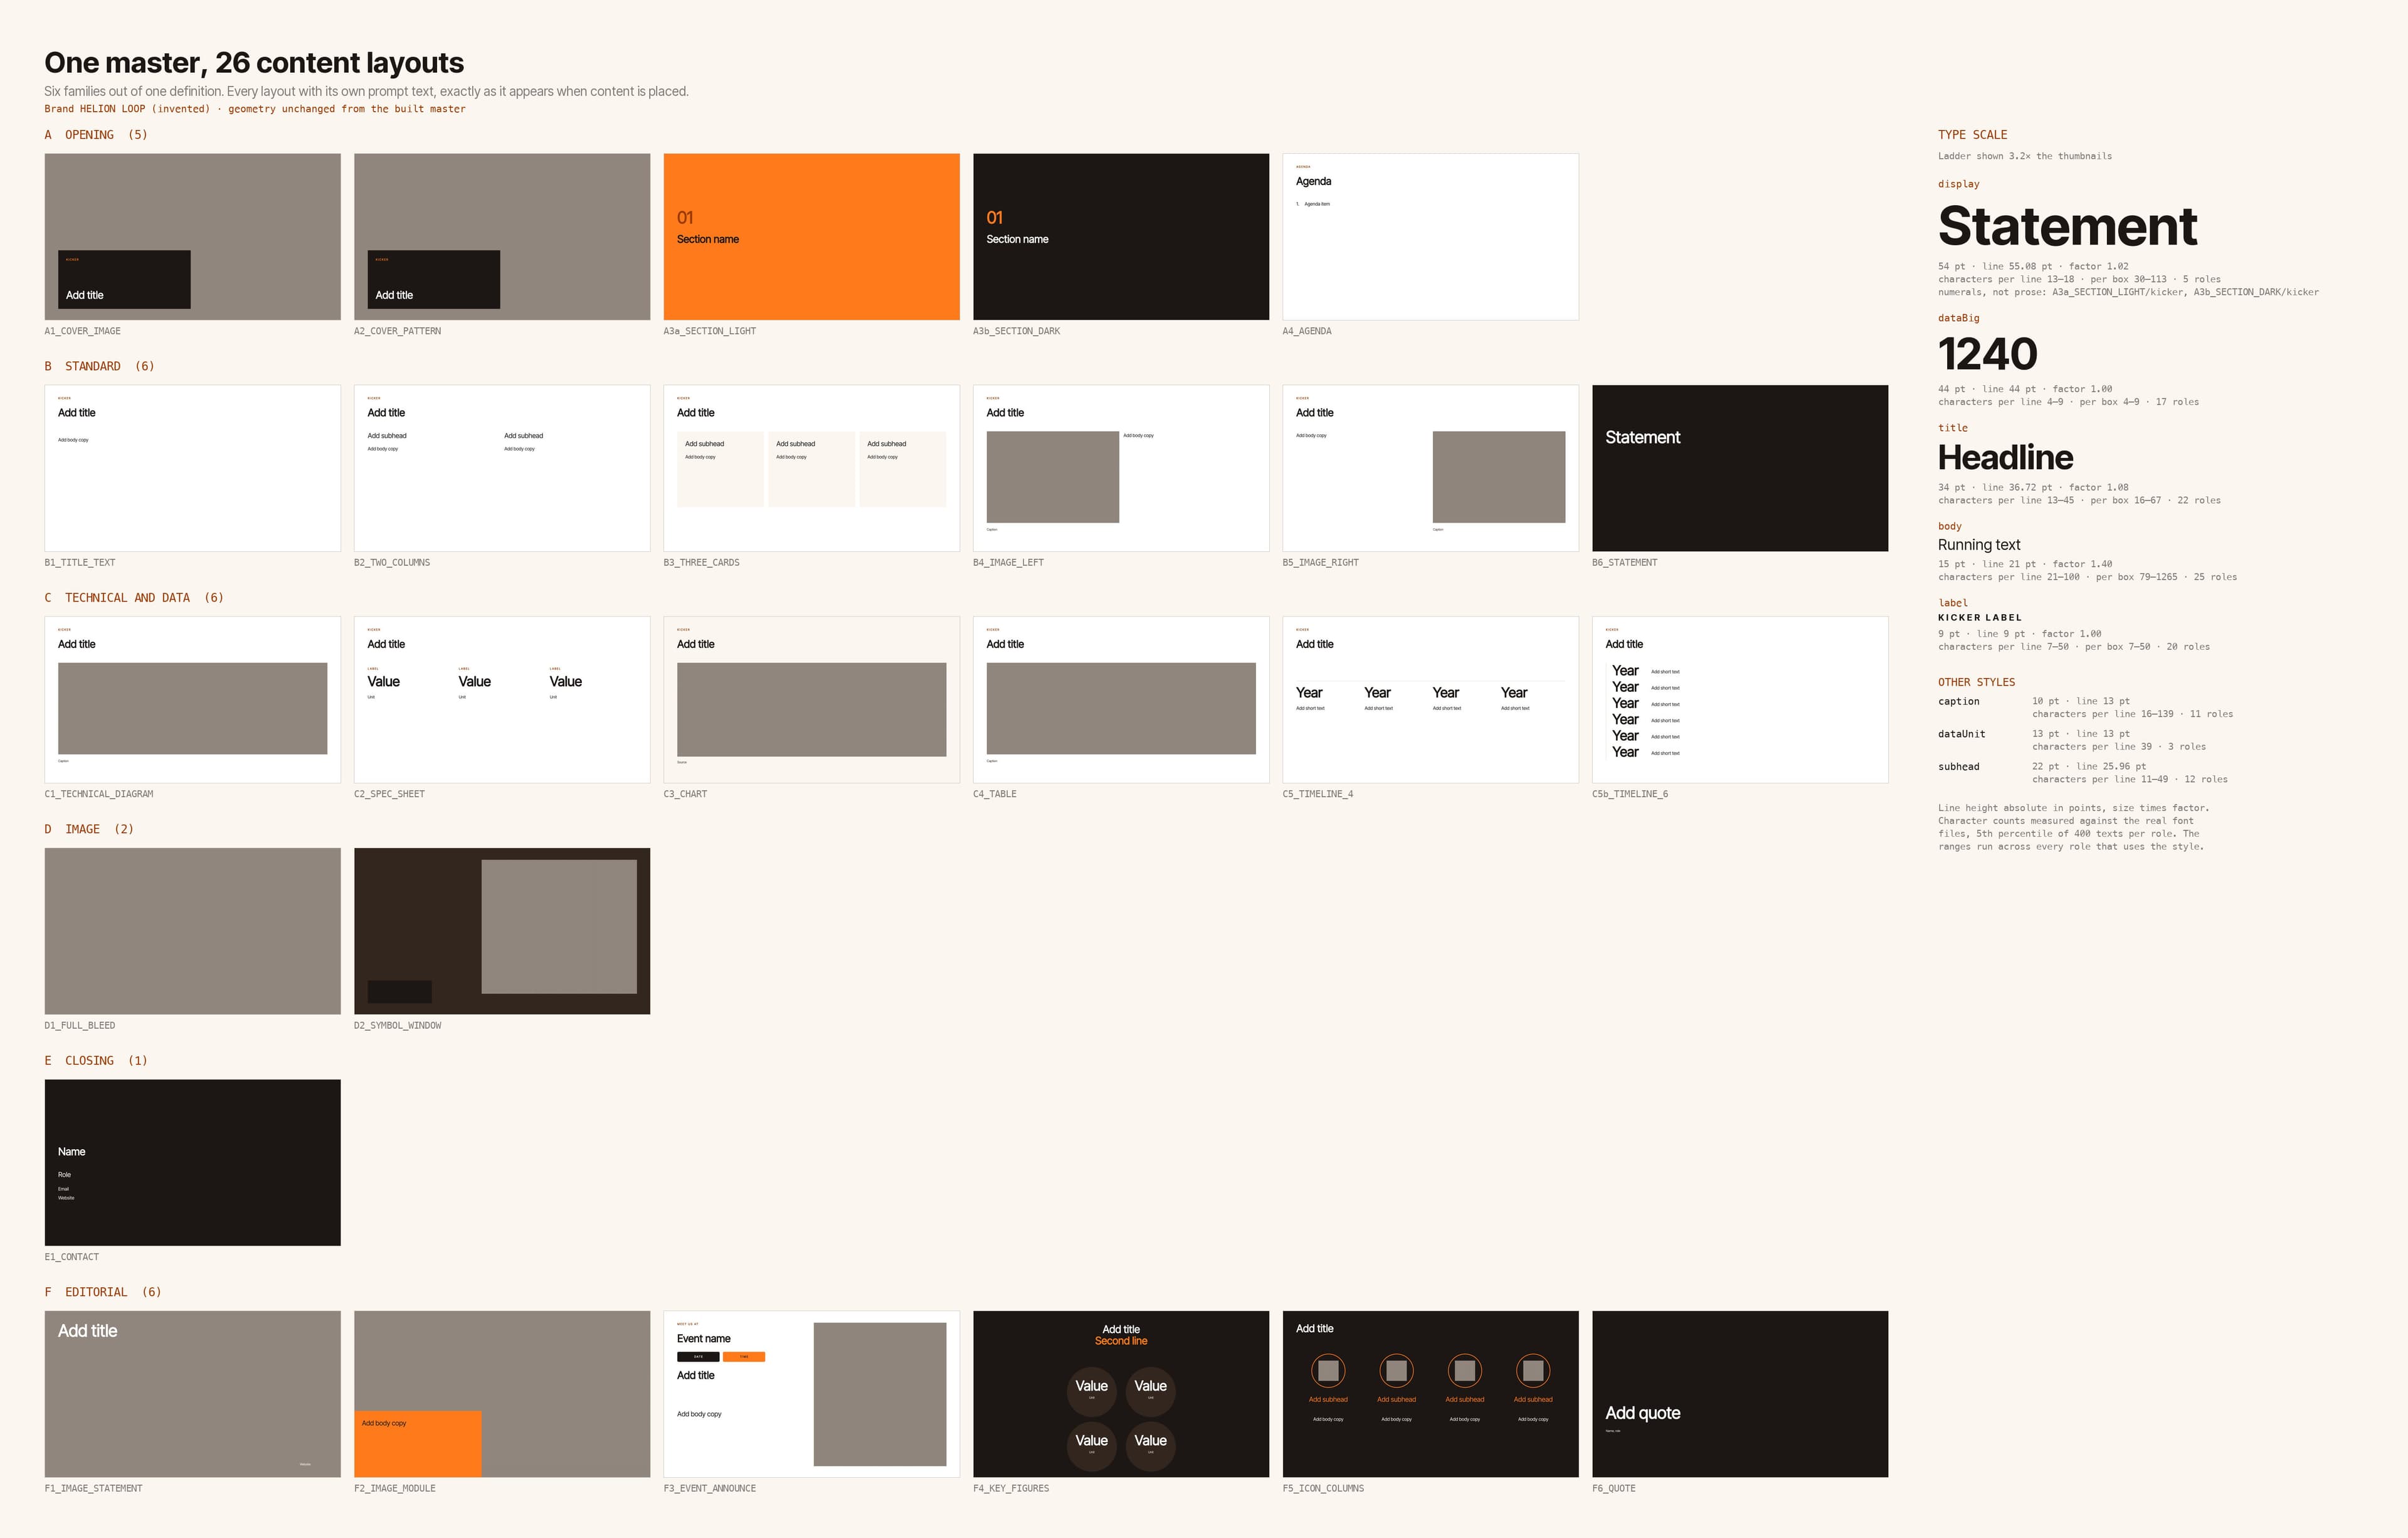
All 26 content layouts out of one definition, with the measured type scale beside them.

A contact sheet of 26 slide layouts arranged in six lettered families on a warm off-white ground, each thumbnail labelled with its layout id, and a type-scale ladder down the right-hand side showing five text styles at size with their measured character budgets underneath.
4870 × 3110 · open at full size

Three layouts up close

Neutral blind content. Two roles are set exactly on their measured budget, so the limit is visible rather than claimed.

A cover slide. A dark colour field sits over the lower left of a plain placeholder surface; inside it a small spaced uppercase kicker line, and a large headline set beneath it in the same field.
A1_COVER_IMAGECover, full-bleed imageThe cover slide. The colour field is the title placeholder and the kicker sits inside it — one element instead of three, and it survives over a full-bleed photograph. The kicker stands exactly on its measured budget of 43 characters and still does not run to the edge: 43 is the 5th percentile of 400 texts, the length at which 19 in 20 fit — not the longest line that would go in. The area shown is a placeholder, not a photograph.

Decisions

Fix every type size and remove auto-fit entirely.

Because
Auto-fit lets each slide settle on its own size, and three editors later the family has no scale left. Fixed steps reverse the relationship: the text adapts to the system.
What it costs
A hard character budget per role, and that conversation with everyone who supplies content.

Express line spacing as an absolute value in points instead of a percentage.

Because
A percentage is a percentage of the font's line height, which lives in a file the recipient may not have. The layouts were all measured as if it were the type size.
What it costs
The setting no longer adapts to the typeface, so a face with tall ascenders sets tighter than its own metrics would ask for.

Repair the cause rather than the six roles anyone could see.

Because
The boxes were never too small; the lines were too tall. Enlarging the visible six would have left the other forty-two wrong and hidden the reason.
What it costs
A larger change than the bug report asked for, and every measured budget had to be recomputed.

Keep the generator and the deck that consumes it in separate repositories.

Because
A master that can be edited while fixing a slide is not a master. The separation makes that impossible rather than discouraged.
What it costs
Two checkouts and a round trip whenever a real deck turns up a real layout problem.

Result

Scope
29 layouts, 115 text roles26 content layouts in six families, plus three instruction layouts the generator builds like any other.
Budget
A character count per roleMeasured against the real font files, not estimated — and the build refuses content that exceeds it.

Contact

In closing

This page is the argument

A deck can describe an interaction model. It cannot be operated. Everything on this page that claims to work can be used right now — filter the matrix, load the live product, open any frame in the series. Nothing is a screenshot of something that exists elsewhere.

The same standard applies to what isn't finished. Two of these five are concepts. They say so at the top, not in a footnote.

How I work

On my own, I hold the whole chain — framing the problem, designing the system, building it. In my professional work, I design complex B2B and enterprise products together with product, engineering, business and international delivery teams. Both are how I work: taking an unclear idea to something you can use, and developing complex products inside an organisation where that chain is shared.